Jina AI search models
Frontier-grade models for ingest and retrieval
Jina AI models preserve meaning from ingestion to retrieval. Get frontier accuracy at a fraction of the compute cost, deployable in your cloud, on-premises, or natively on Elasticsearch.
AI models that preserve meaning from documents to answers
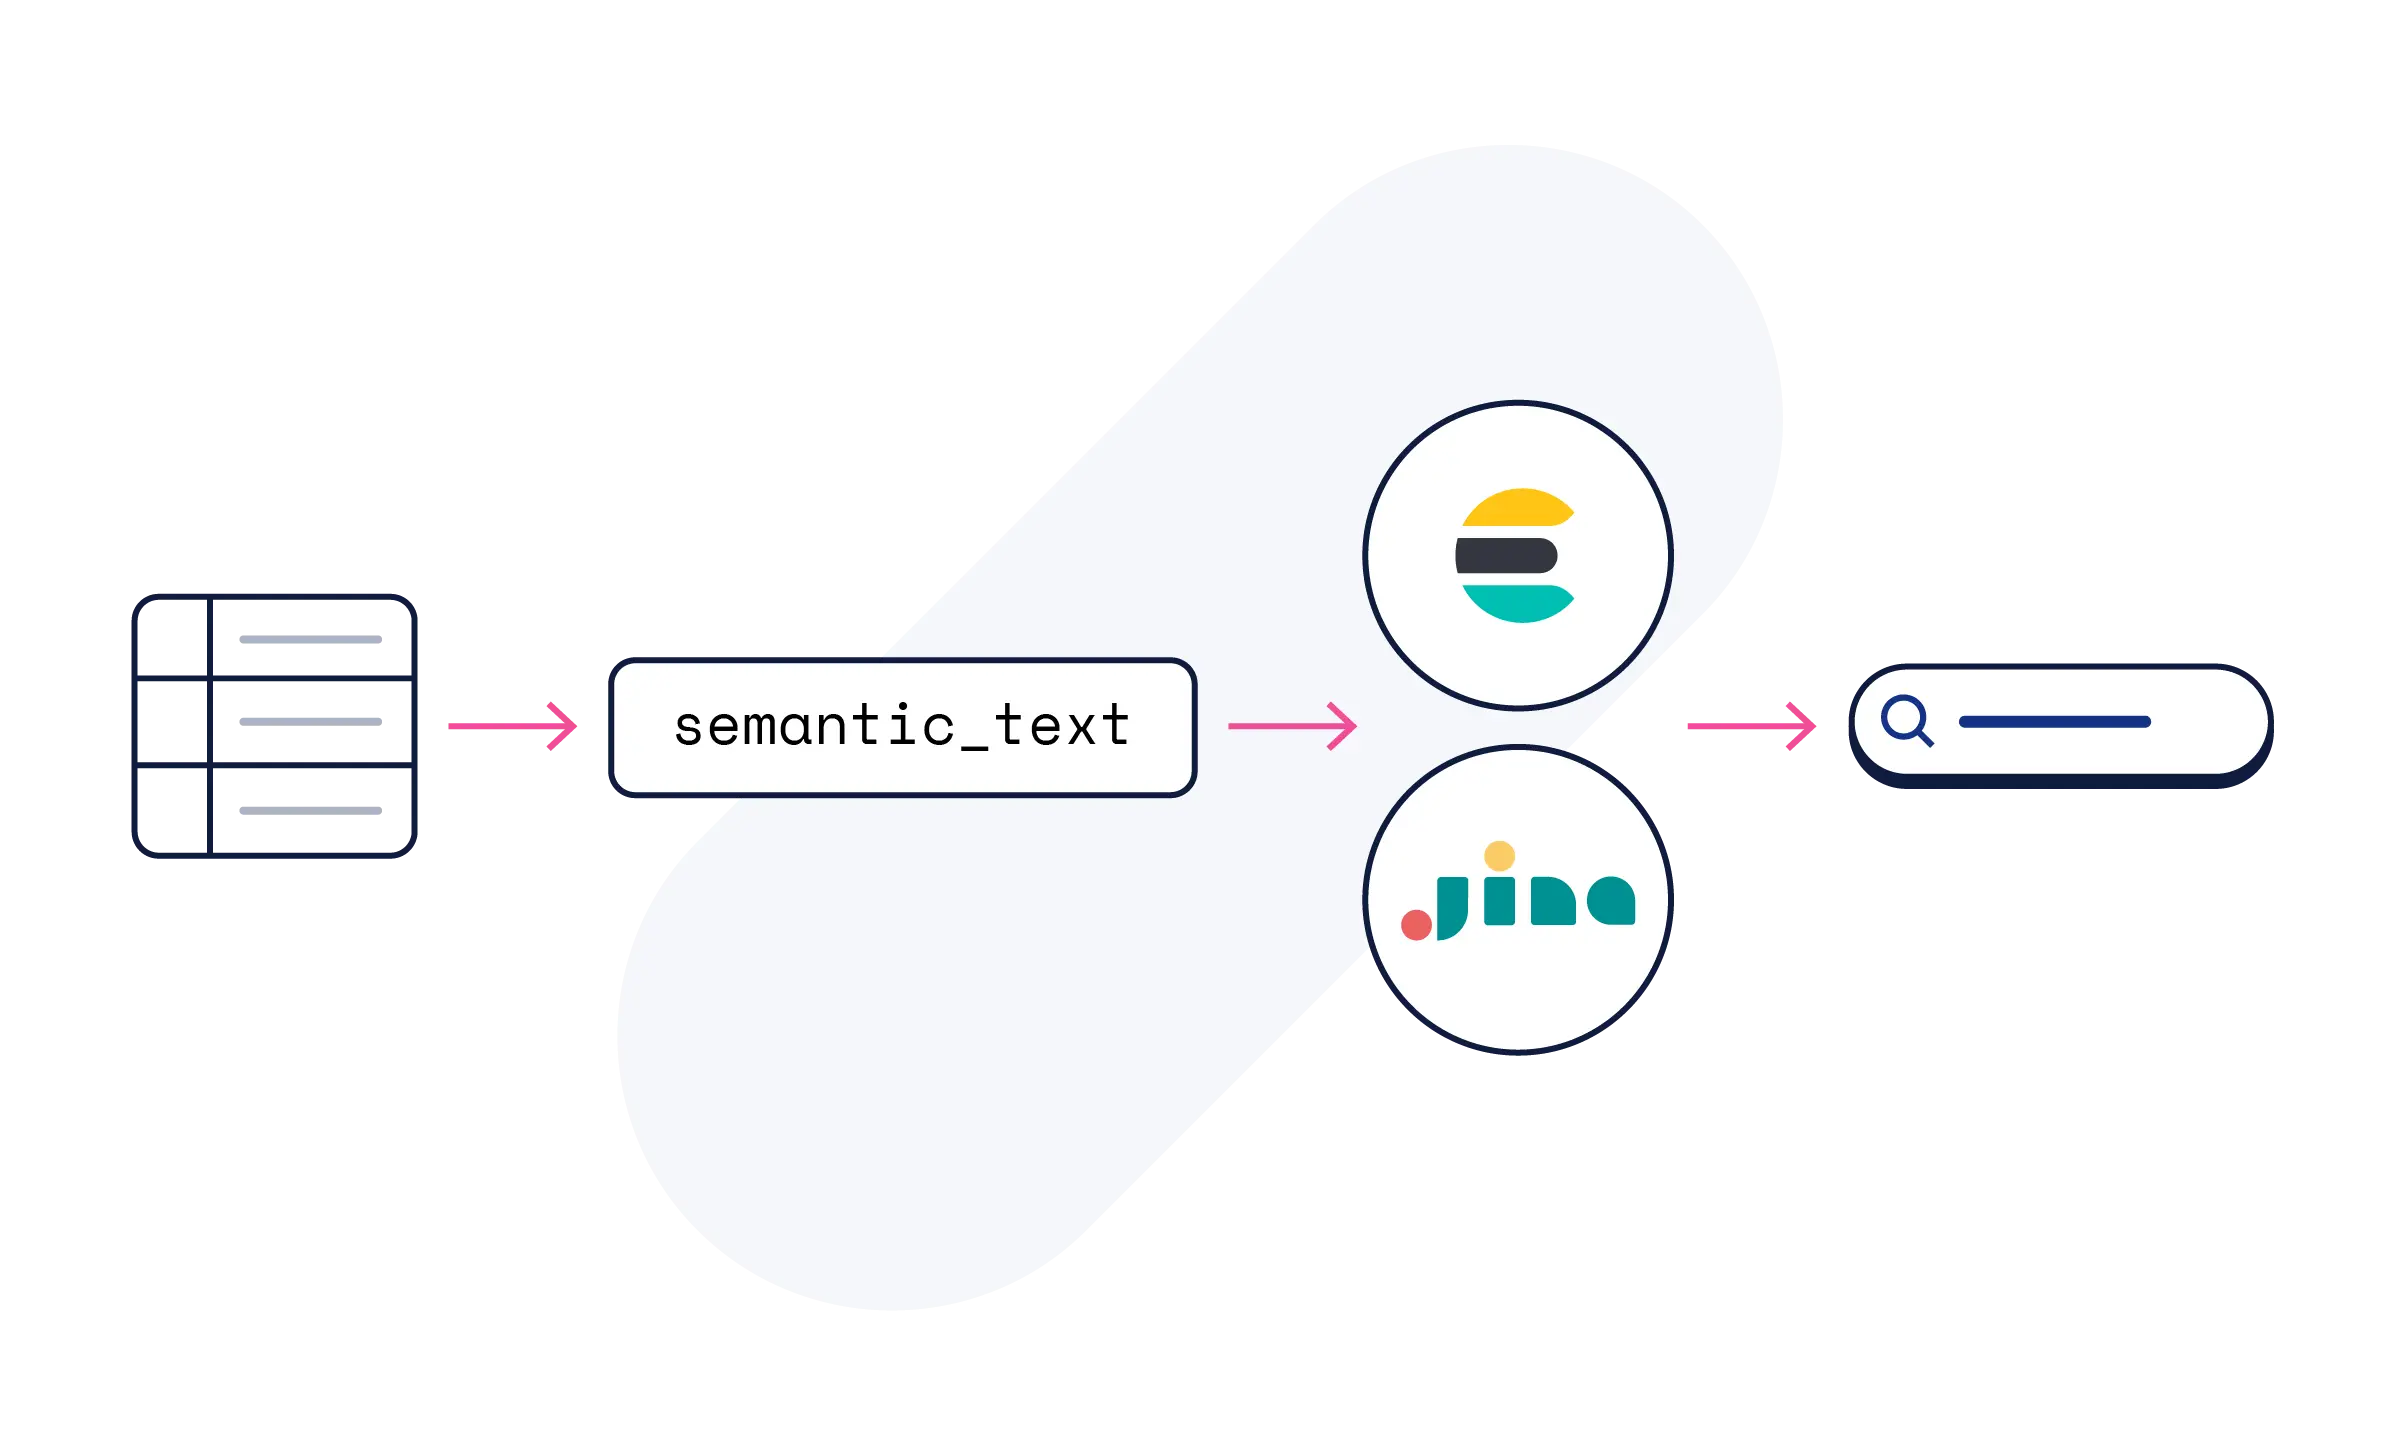
Jina AI develops frontier-grade small models for accurate, cost-effective document ingest, multilingual embedding across text and media, and reranking. It runs natively on Elasticsearch with zero config.


Compact by design, precise by results
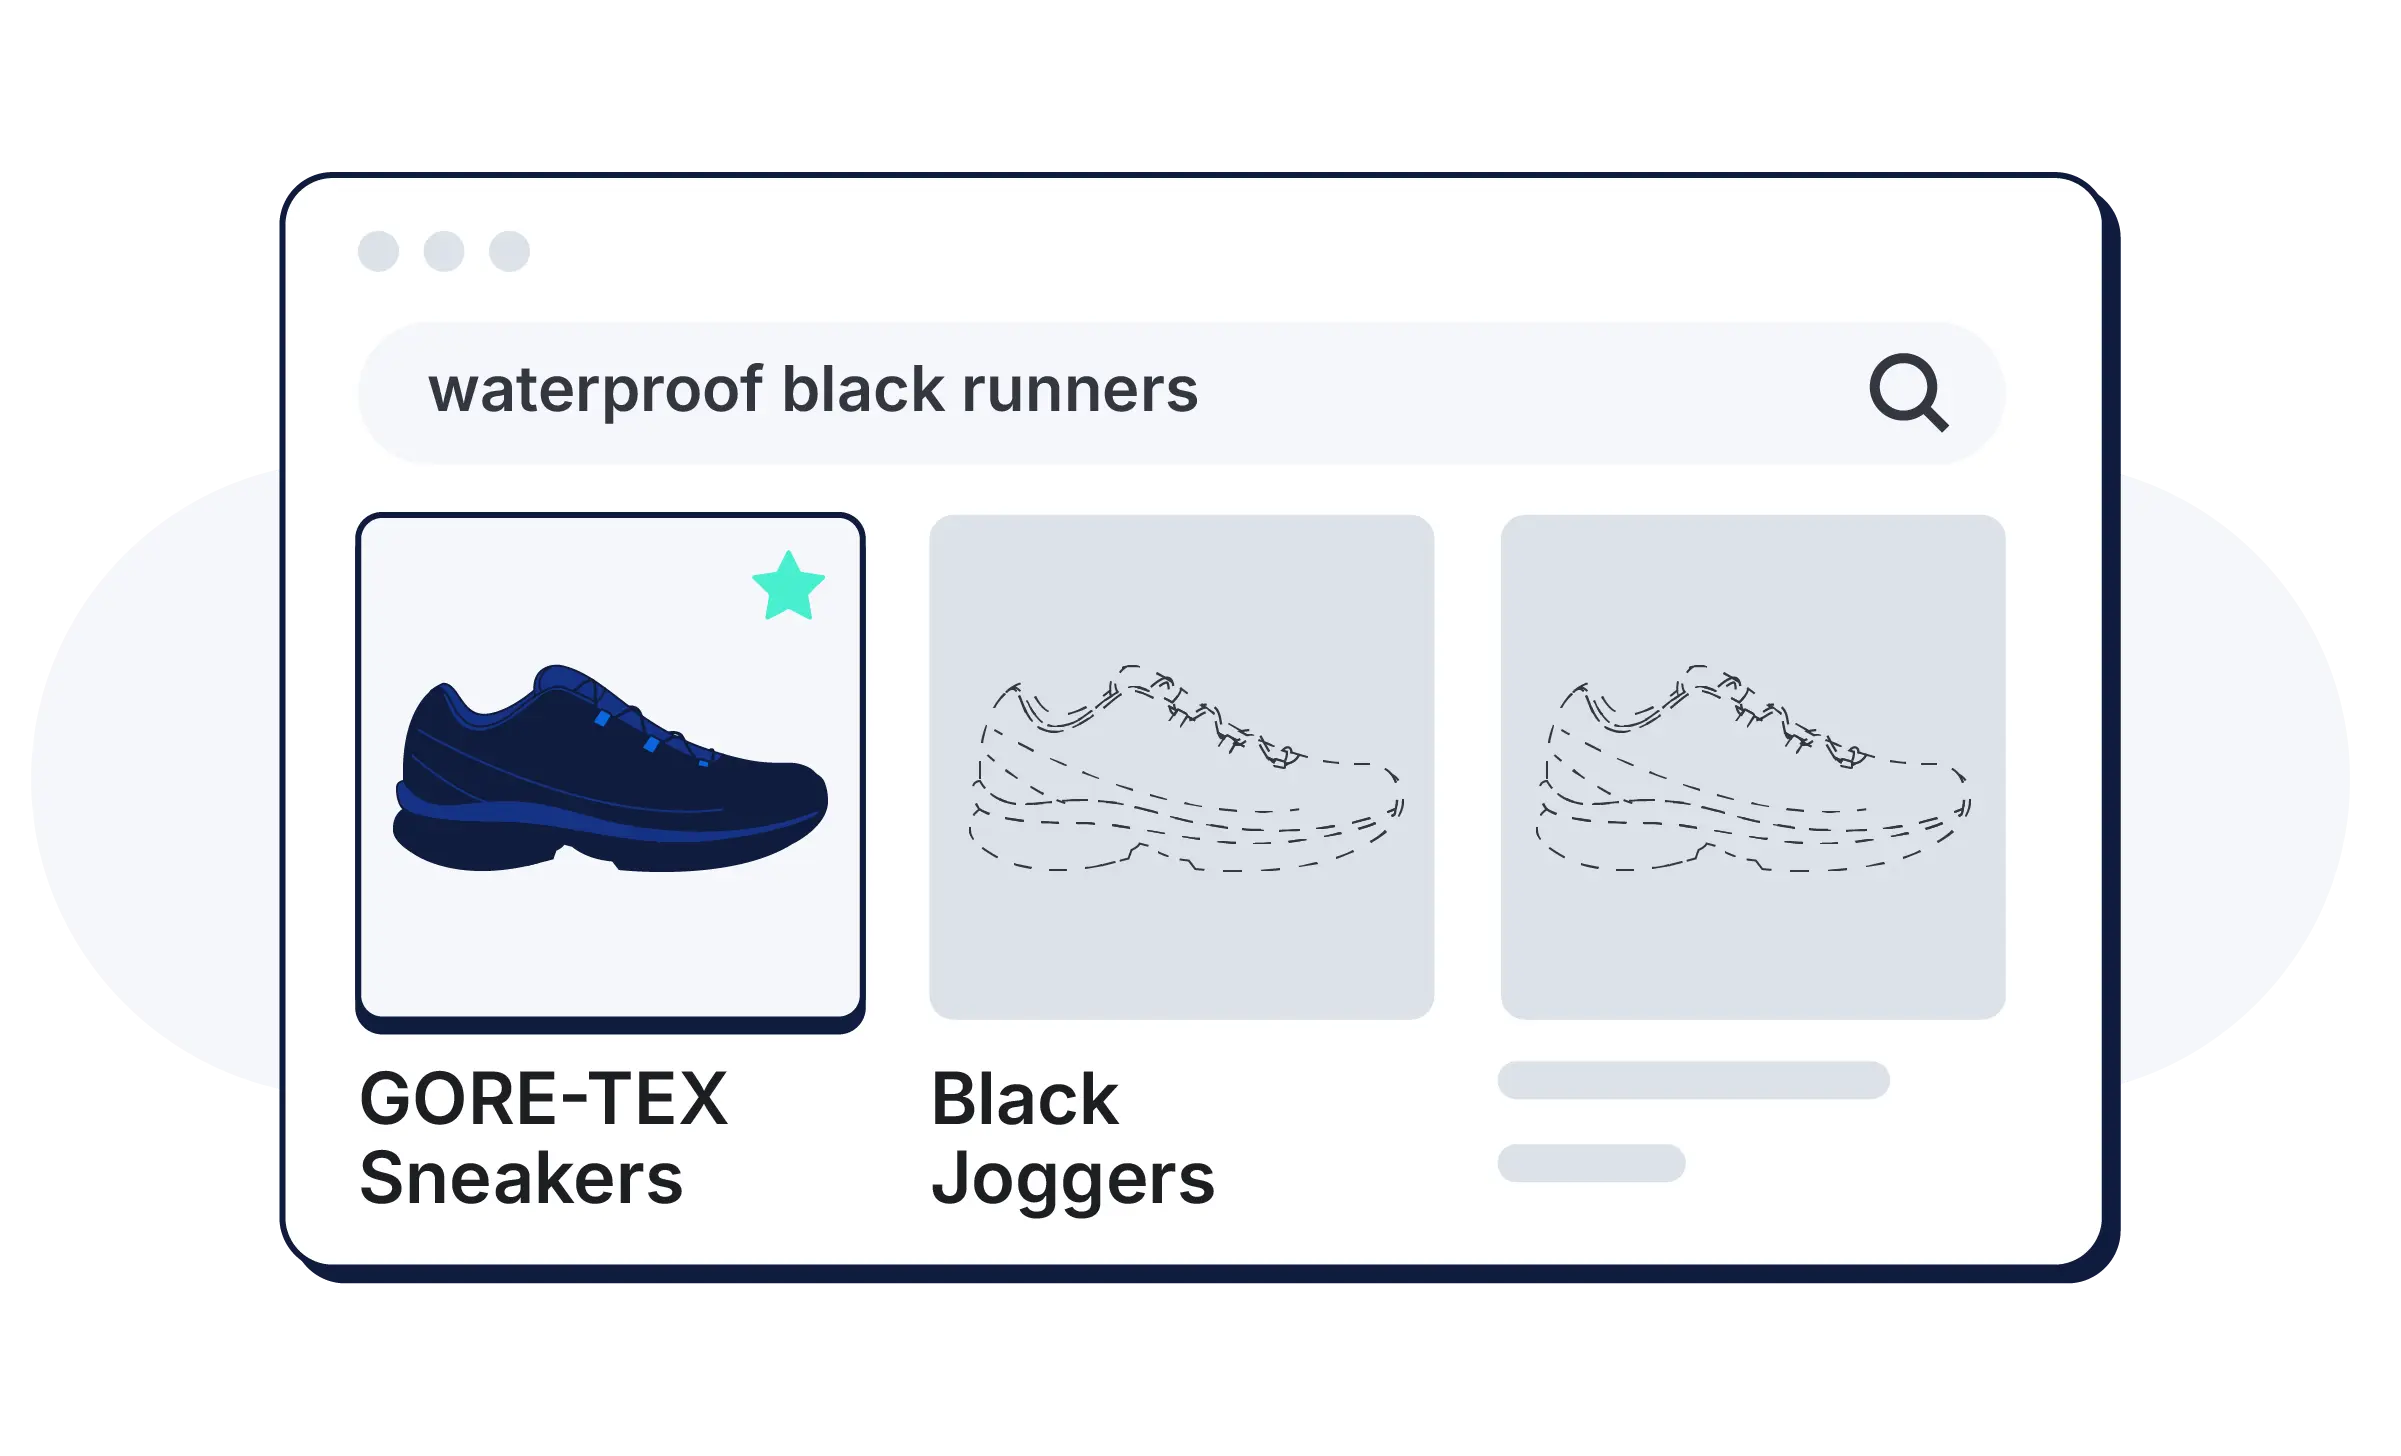
Turn documents into clean, structured data and high-precision search results, in one API.

Use Jina models wherever you build
From fully managed to self-hosted, Jina models meet you where your data lives. Pick the access path that fits.


Our research


Join our open source community
Jina's models are open-weight and freely available on Hugging Face, with millions of monthly downloads. The codebase is public on GitHub. The community has direct access to our developers.
Frequently asked questions
What are Jina search models?
What are Jina search models?
Jina models are open source, frontier AI models for retrieval. They include embedding models for vectors, rerankers for precision, and OCR and readers for extracting and structuring content from URLs and docs.
Do I need AI or machine learning expertise to use Jina models?
Do I need AI or machine learning expertise to use Jina models?
ML expertise is not required. Jina models are available as preconfigured endpoints in Elasticsearch. Map a semantic or semantic_text field, and embedding happens automatically.
How do I get started?
How do I get started?
Jina models are available on Elastic Inference Service on Elastic Cloud included in all trials. Start with defining a semantic or semantic_text field, or explore model cards on Hugging Face for code examples.
Which Jina models are available today?
Which Jina models are available today?
Supported Jina models in Elastic Inference Service are detailed in our Jina models documentation.
How many languages are supported?
How many languages are supported?
Jina-embeddings-v5-omni and Jina-ocr-v1 support 100+ languages. A query in one language finds relevant content written in another, with no translation pipelines required.
How does this relate to ELSER?
How does this relate to ELSER?
Jina embedding models are the default choice for new projects. ELSER will continue to be supported for customers that choose to use it. Both are available within Elasticsearch's hybrid search framework.
Is this a separate product?
Is this a separate product?
Jina search models on the Elastic Inference Service are available to all Elastic Cloud users with consumption-based pricing. No separate license, subscription, or API key required. Jina models can be purchased separately as part of Jina On-Prem.
How does this relate to Elastic's vector database page?
How does this relate to Elastic's vector database page?
The vector database page covers how vectors are stored and searched at scale. This page covers the AI models that generate and rerank them. Together: storage, compute, and application.